Sunday, August 23, 2015

Two Full Weeks of Awesome

I spent two weeks on the road in August, speaking at both the Quicken Loans Technology Conference (in Detroit, MI) and That Conference (in Wisconsin Dells, WI). Since I haven't spent time in that part of the country before, I took some time for sight-seeing as well.

Nothing code related this time; just a few pictures of my time on the road.

Day 1 - Flying Out
With time changes and flight times, it takes a while to travel from Southern California to Detroit. The entertainment started at John Wayne Airport where I saw two planes staring each other down.

Who will win?

Day 2 - Detroit
I had a day to sight-see in Detroit. This is not the blighted city that we often hear about in the media. The downtown area has been going through an amazing transformation over the last 5 years. Abandoned buildings are being renovated, and improvements to public spaces invite people to spend time downtown.

Detroit
Detroit has a view of Canada. It's just across the river.

Windsor, ON - Canada
Later that night, I attended a dinner for the Quicken Loans Technology Conference. Lots of good conversations with some folks I haven't seen for a while, plus good conversations with people I met for the first time.

Dinner
Day 3 - Quicken Loans Technology Conference
The next day was the Quicken Loans Technology Conference. There were lots of interesting speakers, including keynotes by Dan Morales, CIO of eBay and Richard Campbell & Carl Franklin of .NET Rocks.

I had a great time speaking about Clean Code (as I usually do).

Jeremy Talks "Clean Code"
I met a lot of great people at Quicken Loans and got to see first-hand all of the good things that I've heard about the company.

Day 4 - Henry Ford Museum
I had decided to rent a car and drive from Detroit to Wisconsin Dells (it's only about 400 miles -- I'm driving that far this week just to get to the Bay Area in California).

Along the way, I stopped at the Henry Ford Museum in Dearborn, MI. What an incredible place. If you like mechanical things, this is the place to be. I was amazed by things that seem simple now but were a great innovation at the time. For example, here's a hay mower:

Hay Mower
The blades look like a modern hedge trimmer (with an oscillating blade moving over a stationary one). But it was geared into the wheel, so the blade would move as the wheel turned. Really cool stuff.

Plus, planes, trains, automobiles, tractors, plus the Dymaxion House by Buckmeister Fuller. If you're ever in the area, you need to stop by.

Day 5 - Indiana
The next day was mainly travel. I drove across Michigan and into Indiana. It was beautiful and green along the way.

Welcome to Indiana

Day 6 - Wisconsin
The next day was more travel. I drove by Chicago, IL and Milwaukee, WI. It was great to see the skylines of the cities (and I was looking forward to going back to Chicago the following week).

At a rest stop in Wisconsin, I saw that they take their recycling really seriously.

Recycling

Day 7 - Madison
I stayed in Madison,WI and went to the Henry Vila Zoo. It's a free zoo that has quite a selection of animals. I spent quite a bit of time with the goats (someday, I'll have goats of my own):

GOAT!

I've always loved goats, and they seem to like me as well. They would run over to folks who had food to give them. But once the food was gone, they would come back to me for scratches.

Then I drove on to the Kalahari Resort in Wisconsin Dells -- the location of That Conference. I spent about an hour in the registration line that night. It sounds like a long time, but it gave me a chance to talk to 10 new people. If you want to hear more about that, be sure to tune in to .NET Rocks! on September 3rd, where I'll be talking about becoming a social developer (or check out this recent article about That Conference).

Day 8 - That Conference
That Conference was a really great event. I met tons of great people and saw a lot of great tech.

Day 9 - That Conference
There were tons of great sessions, and a few pearls of wisdom. Here's one from Stephen Cleary in reference to asynchronous programming:

Every Time You Use Async Void, Rory Dies
And here's something from David Neal that we should never forget:

You Don't Need Permission to be Awesome
Later that night, there was a party at the water slide park at the resort. I think I figured that I hadn't been on a water slide for over 20 years, but I didn't let that stop me. I went on pretty much everything, including the 4-story, straight down slide. I had chlorine in my sinuses for the next 2 days. But it was totally worth it.

Day 10 - That Conference
The last day of That Conference, I was mostly on the hallway track -- speaking to folks I had met during the week, and hosting an open spaces session with Ondrej Balas on building your brand as a developer.

I finally got to speak on the last day of That Conference. In fact, I presented during the last breakout session of the conference.

Jeremy Talks "Clean Code" (again)
Thanks to all the people who came. We had a great time together. Here are a few tweets from that afternoon:


There's a lot more that I could say about That Conference, but we'll save that for another day. I met a ton of great people, got to catch up with a few old friends, and had some really amazing conversations. I'll look forward to going again next year.

Day 11 - Circus World
After That Conference wrapped up, I had a few days to make my way back to Chicago where I would be flying out.

I spent a day at Circus World in Baraboo, WI. This was the winter home for the Ringling Bros Circus, and the site dates back to the early 1900s.

Novelty Musical Intruments
I got to see the novelty musical instrument show, which included this interesting contraption. The cranks were attached to hammers that struck a xylophone-type tuned bar. In addition, there was a big top show with unicyclists, clowns, performing dogs, camels, elephants, and aerialists.

Later that day, I went to the Timbavati Wildlife Park, where I got to pet a kangaroo:

Kangaroo
And I went to the races as well:

Pig Races
Day 12 - Wisconsin State Fair
The next day, I spent the day at the Wisconsin State Fair (just outside Milwaukee). I was especially happy to be there since I was missing the Orange County Fair back home.

Wisconsin Cows
This was much different from my local fair. For example, at the Orange County Fair, most of the animals are 4-H or FFA projects. The Wisconsin State Fair had tons of animals from working farms. There were 2 cow barns, a 2-story horse barn, a sheep barn, a goat barn, and a bunny and chicken barn, plus a big covered arena (which was nice since it was hot and sunny out).

While in the arena watching a horse competition, I heard someone say, "I'm more of a cow person. I would buy a cow if I could afford one." Not something I'm used to hearing.

There was also a Cream Puff building where they were making tons of fresh cream puffs (and selling them just as fast as they made them).

Cream Puffs being made
Really tasty. Lots of other great stuff to eat, too.

Day 13 - Little Amerricka
The next day, I found myself in Marshall, WI at the Little Amerricka amusement park. This was an awesome little place between the corn fields and the cemetery. Lots of rides and lots of fun. The Mad Mouse was a historic little ride that is a lot more terrifying than it looks.

Mad Mouse at Little Amerricka
This is one of those rides that was made before lawyers existed. You just get in the little sled with wheels and hang on -- no lap bars or seat belts.

In addition, a great wooden roller coaster, a toboggan ride, a "monorail", ferris wheel, bumper boats, haunted house, mini golf, and lots more. I had a really great time. And I was hot and exhausted by the time I was done. A great place to visit.

Day 14 - The Field Museum
My last day was in Chicago, IL. Rather than trying to park in the city, I decided to take the "L" in.

The "L"
This was a great system to use. It was easy, the trains and stations were well marked, there was good air conditioning, and the station announcements made it easy to know where to get off. As an aside, I always thought the Chicago train was referred to as the "el" -- short for "elevated train" -- I stand corrected.

This was also a great way to see the city. There were good views from the elevated track, and I got to see a variety of neighborhoods (at least until it went underground near the "Loop").

The goal was The Field Museum. I've wanted to go there for many years for one reason: to see Sue the T-Rex. And I was very excited when I finally saw her:

Jeremy and Sue
This journey started many years ago when I first heard about Sue on television. Then a bit later, I visited the Black Hills Institute in South Dakota (the folks who found Sue). Then I got to see a replica of Sue in Orlando, FL a few years after that. I was excited to reach the end of the journey.

There was lots of other cool stuff at The Field Museum. This little picture really made me laugh, though:

Oxygen
This is showing how photosynthesis in early cells resulted in the oxygen in the atmosphere. I got a chuckle out of the cell farting out oxygen like "What are you gonna do?".

Out one of the windows, I got a good picture of the Chicago skyline.

Chicago, IL
Day 15 - HOME
I ran myself pretty ragged during these two weeks. So, I was really glad to be headed back home. I didn't get to do an architectural tour of Chicago (there are tons of really cool skyscrapers), but I'm sure I'll have plenty of other opportunities to go to Chicago. And I bought a "Pocket Guide to Chicago Architecture" at the airport. So I have a good reason to go back.

I'll get back to the technical articles soon. Plus, my YouTube channel just passed 1,000 subscribers, so I'd better produce a new video soon. Until then...

Happy Coding!

Tuesday, August 18, 2015

Reconciling Clean Code and the Startup Mentality

Last week, I was at That Conference, and it was an awesome week (more on that later). But it was also a bit awkward. On Wednesday, the keynote by Max Lynch (co-founder of Ionic) was about startups and getting functionality to the users (or potential users) as quickly as possible. It was a great talk about some key features of successful projects.

A big theme to this was "It doesn't matter what your code looks like." The awkward part is that I was speaking about Clean Code and the importance of caring about the readability of code later that day.

Fortunately, a lot of people showed up for my presentation, and we had a really great time together. But I did get an interesting question afterward from someone who worked at a startup:
How do I reconcile "It doesn't matter what the code looks like" with the principles of craftsmanship?
The developer believed in craftsmanship and readable code, and he was a bit distressed that his boss was saying that they had to do things fast and dirty. As a bit of a surprise to myself, I actually had a good answer to give (at least I thought it was a good answer):
Treat the version 1 product like a prototype.
Let's explore this a bit more.

The Importance of Moving Quickly in Multiple Directions
I understand the startup mentality of "it doesn't matter what the code looks like" -- but with full understanding of the consequences of that approach.

The problem is that we only have an idea to start with, and we're not even sure if anyone will be interested in it yet. So we put together just enough code to get things working. And a lot of times, we don't even get that far; we just create a landing page to see if anyone is interested in the product before we even write a single line of code.

And once we start coding, we cannot invest too much time or effort into this. If it is a complete flop, we discard the code and move on to the next idea. We don't know what we need at this point. We're really just exploring. Ultimately, we're working toward a minimum viable product, which is just enough functionality to be useful to someone.

Even then, we don't know what feature will really resonate with our users, so we have to be ready for unexpected responses and to move quickly in another direction.

Just a Prototype
The only way we can use this approach is if we treat this code as prototype code -- even if we are releasing it to the users. This is our exploratory code -- where we figure out what excites our users and differentiates us from the rest of the pack.

There Will Be Problems
When we write code like this, there will be problems. We will have bugs that are hiding in the code. We will have issues scaling for more users. We will reach a point where it is difficult to add a new key feature.

And this is the point were "it doesn't matter what the code looks like" really starts to cause us pain. The best thing to do is discard what we have and write the code for our real product based on the prototype.

Clean Code Does Matter
It's really easy to fall into the trap of thinking that clean, readable code doesn't matter. After all, if we can be successful without it, who cares?

This works short term, but things fall over in the long term.

Once we have our viable product, and we start coding "for real", we need to pay attention to craftsmanship principles. We have to make sure that we don't introduce bugs in our code. And we do this through automated testing (the proof that our code does what we think it does) and through readable code (if the code is easily readable, then the bugs have nowhere to hide).

In addition, since we now know what features make our application successful, we can leave spots for abstractions and extensibility points so we can easily add new features.

And this is where we start to think about the long-term viability of our product. If we treat our version 1 as the real version rather than the prototype, we're just setting ourselves up for a lot of pain. But if we take the learnings from the prototype to then create the actual product, we can reap the benefits of our quick, maneuverable process and use them to create a sustainable product.

Final Words
In the Wednesday keynote with Max Lynch, the focus was really on starting many companies (one after the other, and sometimes several at the same time) based on ideas that we don't know will work. We need to figure out what resonates with our users quickly so that we can focus our efforts.

So, my advice to people who are coding "fast and dirty" and don't feel right about the process: think about this as a prototype. It is an exploration of what might be useful. And just because we release that product to our users does not make it any less of a prototype. Expect to discard this code once we have gotten what we need to know from it.

It Does Matter What Code Looks Like
Ultimately, it *does* matter what the code looks like. Having readable code is what makes it easier for us as developers to make changes to meet our users needs. If we can't quickly meet our users needs, then we've failed. If we don't go back to replace that prototype code, then we'll end up falling over at some point.

If we create a mess so that we can get some learnings out of it, that's fine. But we can't leave things that way. For long-term viability, we need to think about the quality of our code which ultimately impacts the quality of the product.

Happy Coding!

Friday, August 7, 2015

When Does DRY Become ARID?

The DRY Principle is a great thing to keep in mind:
The DRY Principle
Don't Repeat Yourself
But like all principles, we need balance. Otherwise we might find we've gone from DRY to ARID:
ARID Code
All Readability Is Dead
To me, readability is king. Sometimes I will pick a not-completely-optimized way of writing code so that it is more understandable. (Obviously, if I really need speed optimized code -- such as tight loops or other processes -- then that will get prioritized.) Let's see why we need to watch out for over-doing DRY and straying into ARID code.

Challenged By a Friend
I'm a big fan of the DRY principle, and that's because it's caused me a lot of grief in code I've dealt with. And this is one of the reasons I spend time sharing my stories with other developers (see "Clean Code" and "Abstract Art").

One of my friends -- a developer I worked with for many years -- recently watched my Clean Code presentation, and he made a comment about the refactoring part.

"I don't think you went far enough... You're violating DRY."

I'm always up for some exploration, so let's take a look at the code.

The Original Refactoring
If you want to watch the refactoring in video, here's a link to the right spot in the recorded presentation: YouTube - Clean Code 46:03.

In the sample, we start with a simple (but a bit difficult to approach) method:


Then we extract a couple of methods to hide some details and add some good method names to let us know what's going on:


This makes our "Initialize" method much easier to understand. If we need to know how we "get the service from the container", we can drill into that method. Otherwise, we can simply move on.

A Bit Drier
My friend pointed out that there is duplicated code in the two extracted methods. So this is where we should concentrate our efforts.


When we look at these a bit closer, we see a lot of similarity. We have conditions based on "IsRegistered" to see if an item is in the dependency injection container. Note that these are not *exactly* the same. The first method has a "CurrentOrder" string as a parameter; the second method has no parameter.

If the object is not in the container, then we throw a MissingFieldException (same exception with a slightly different message).

Then we resolve the actual item from the container. Again, one of the methods takes a string parameter, and the other does not.

To help us get rid of some of this duplication, we can combine them into a single method with the help of a generic type parameter. Here's a first stab at this:


Now we have a single method that returns a generic type ("T"). But we really haven't eliminated the duplication. We simply have 2 conditional blocks based on whether we have that optional string parameter. If we have a string parameter (like "CurrentOrder"), then it is passed to the "IsRegistered" and "Resolve" methods. And it is also used in the message of our exception.

If there is no parameter, then we use the name of the type itself in the exception message.

With a little more understanding of how the underlying methods work, we can eliminate some duplication:


This takes advantage of the fact that if we call "IsRegistered" with a "null" parameter, it works the same as if we had no parameter. The same is true of "Resolve". It was very easy for me to verify this functionality because I have unit tests in place that test both the success state and the error state for this.

We still need to use the right string for our exception message. So for that, we create a variable ("missingObject") that we can populate with the parameter or the type name as applicable.

Using the Drier Method
Now that we have our drier method, we need to actually use it in our code. Let's update our "Initialize" method:


All of our unit tests still pass, so we know that this code is functionally the same as we had before, but have we made the readability better or worse?

This exposes some details that we don't have in the other version. For example, we see that the model is of type "CatalogOrder" (which we could tell from inspecting the "_model" variable as well). But it also tells us that the model is referred to as the "CurrentOrder". Is this important? Or does it just get in the way?

Let's put the methods side by side:

Original

A Bit Drier

Personally, I prefer the original version in this case. We don't need the details here; that's the reason we extracted the methods to start with. In addition, I know the environment that this code came from. It's based on real code and a real situation. Based on my understanding, the original refactoring is a better fit for the developers who would be maintaining the code.

As with all of our best practices, this is a matter of balance. For a bit more, see Beware of "Never" and "Always".

Truly ARID
I would not consider either version above to be unreadable, but readability is always at the top of my mind. The primary reason for this is that in addition to seeing violations of the DRY principle, I've seen people take this much too far. The result was something completely unreadable.

Here's an example. I was working on a WPF project, and we had several value converters to get our UI working the way that we needed for our users. (Value converters are one of the great things about data binding in WPF -- it let's us do cool things like bind a color in our UI to a date property in our data.)

Someone got tired of the proliferation of value converters, so they decided to create "one converter to rule them all". The idea was to have one value converter that had all sorts of options that could be provided as parameters. We'll look at just a little bit of this code (unfortunately, there was much, much more).


This is the main "Convert" method. And we can see that there are a couple of properties used in this method: StringFormat and FalseText. And there are a couple of methods called as well: IsStringFormatConversion and Match.

Let's take a look at the Match method:


Yikes. This contains more properties: ConditionalText, IsNullCompare, IsStringCompare, and IncludeEmpty. The mixture of "&&" and "||" also makes the logic extremely difficult to follow.

But worse that this is that the converter was confusing to use. Here are a couple basic examples:


These only use two of the possible parameters: ConditionalText and IsStringCompare. But there were examples that used many more.

The big question is "What do these converters actually do?" And that's the problem. Just by looking at the usage, I have no idea what's going on. I would need to dig deeper.

This code has definitely crossed the line into ARID.

Balance in Everything
As developers, we have to constantly find the right balance. This could be weighing the pros and cons of a particular tool. It could be finding the balance between readability and testability. Sometimes it is finding the sweet spot between speed and memory footprint.

Sometimes these choices are clear cut. But often, they are subjective -- especially when we're talking about readability. Because we always have to ask, "Readable by whom?" Readable by a senior developer? Readable by a new developer? Readable by our users?

In the example we looked at today, I could see arguments being made either way. I have a bit more insight since this is based on real code, and I know the developers who needed to understand the code. Because of this, I erred on the side of simplicity. These projects had a lot of new concepts to this team (DI, XAML, delegates, and a few more), so I would simplify wherever possible.

The decisions aren't always easy. But that's part of the fun of this type of work.

Happy Coding!

Saturday, August 1, 2015

August 2015 Speaking Engagements

The summer is going by quickly. We're already at the end of July. I've got a busy August (which is good). I'm looking forward to some great events.

Wednesday, August 5, 2015
Quicken Loans Technology Conference
Detroit, MI
Topic: Clean Code: Homicidal Maniacs Read Code, Too!

I'm looking forward to speaking at Quicken Loans. I know some folks who work there, and they rave about the environment and the company philosophy. It will be great to see that in person.

As a reminder, I'm available for corporate events. So if you have a company tech event, I'd be glad to talk to you about coming out. In addition to presentations, I also do half-day and full-day workshops for those who want to dive a bit deeper.

Monday - Wednesday, August 10-12, 2015
That Conference
Wisconsin Dells, WI
Website
Topic: Clean Code: Homicidal Maniacs Read Code, Too!

I'm very excited about being part of That Conference this year. I've heard great things about it in the past, and this will give me a chance to experience it for myself. There are a ton of great sessions lined up as well as a keynote from Uncle Bob. Plus, it takes place at a resort with a waterslide park. Water Slides > Powerpoint Slides.

Thursday, August 27, 2015
SouthBay.NET
Mountain View, CA
Meetup Event
Topic: Unit Testing Makes Me Faster

I'm headed back up to the bay area later in the month. I'm talking all about how unit testing has made me a faster developer. I've been thinking about this topic for a long time, and it's finally taken shape. Look forward to a lot of fun and hopefully enough hard facts to convince you to take another look at unit testing.

Keep checking my website (or follow me on Twitter @jeremybytes). I often have late additions to my calendar, so there may be something near you.

A Look Back
My schedule was pretty light in July, but I ended up with back-to-back speaking days. At Inland Empire .NET in Riverside, I managed to show that you don't have to be an expert in a technology to talk about it. I had a lot of fun showing people how to get started with Git, and there were a couple folks who were using it regularly, so they helped out with some of the more advanced questions. And that's why I called my talk "Getting Started with Git". I'm still relatively new, but I'm hooked on it now.

Inland Empire .NET (the orange shirt keeps people awake)

The next night, I was in downtown LA for C# Entertainment. Reynald Aldophe came up with an interesting concept: combining tech and stand-up comedy. The event was a lot of fun. Christian Zezza provided us with some amazing guitar playing. Then I talked for a bit about tasks and asynchronous programming. To round out the evening, Chris Fairbanks provided the comedy. (I know everyone was relieved to hear that I was not doing the comedy or the music.)

Keep track of C# Entertainment and check out an upcoming event.

A Look Ahead
It looks like I'm going to stay busy. I really love to speak, meet new people, and catch up with old friends. In September, I'll be in the Phoenix area to speak at 2 of the .NET groups there. And in November, I'll be speaking at Visual Studio Live! in Orlando. It's still really cool to see my name on the speaker list. I'm really looking forward to that.

Hopefully I'll see you at an upcoming event. If you don't find one nearby, contact me. Let's see if we can set something up in your area.

Happy Coding!

Thursday, July 23, 2015

Pay Attention to Where You Create Progress Objects

When dealing with Tasks, where we create our Progress<T> objects affects where our progress handlers run (or don't run).

Let's jump into a sample. Our application is pretty simple (and you can find the code on GitHub: jeremybytes/progress-task). Here's the UI:


What we're doing is starting a new Task and then reporting progress back to our UI. We've got our code in the code-behind to see how the Progress<T> object reacts. This isn't ideal, but it's what we have for small apps, and it will let us see where we can run into issues.

The Basics
We've got a couple of methods that we want to use (these are in MainWindow.xaml.cs along with all the other code):


The "StartLongProcess" method is what we'll put into our Task. This is pretty simple. We have a "for" loop that goes from 0 to 50. Then inside the loop, we send back the value of our indexer through the progress object. Finally, we Sleep for 100 milliseconds to add some delay to our process. We'll pretend that that "Sleep(100)" is actually processing data or some other operation like that.

When "progress.Report" is called, it runs the "UpdateProgress" method (we'll see how these get associated in just a bit). The parameter "message" is the value that is passed in to the "Report" method above. Since we have a "Progress<string>", our parameter will be a string type.

So ultimately, we'll take the value of the indexer from our "for" loop and put it into a text block in our UI.

Progress<T> in "Bad Progress"
We'll start by looking at the code we have on our "Bad Progress" button:


This creates and starts a new Task by using "Task.Run" (for more information see "Task.Run() vs. Task.Factory.StartNew()").

We create a task that will execute the "StartLongProcess" method. This takes an "IProgress<string>" as a parameter (as we saw above). We use "new Progress<string>" to create the progress object. "Progress<string>" implements the "IProgress<string>" interface, so we can pass it to this method as a parameter.

The Progress constructor take a delegate as a parameter. This is the method that will be called when we "Report" progress. Notice that this is the "UpdateProgress" method from above. This is how our progress object gets associated with the progress handler.

Let's run this code to see what happens. If we click the "Bad Progress" button, we get the following message:


As we can see, we're getting an "InvalidOperationException". The additional information tells us what we need to know: "The calling thread cannot access this object because a different thread owns it."

This means that our "UpdateProgress" method is not running on the UI thread. When we try to directly interact with UI elements from a non-UI thread, we get this error.

We can fix this by marshalling this call back to the UI thread. But there's actually an easier way to get this code to work.

Progress<T> in "Good Progress"
What's the easier way? Let's look at our "Good Progress" button for a clue:


The difference here is subtle. We're still calling "StartLongProcess" inside our Task, and we're still creating a "Progress<string>" object that points to our "UpdateProgress" method.

But as we'll see, our results are completely different when we click the "Good Progress" button:


This code actually works as expected! We can see our text block has the value of "22" (I grabbed a screenshot in the middle of the process).

This calls the exact same "UpdateProgress" method, but it has no trouble interacting with the UI elements. Let's focus on the differences between our 2 methods.

Where We Create Progress<T> Matters
Here are both methods together:


What we need to pay attention to is where we create the "Progress<string>" object in each case.

In the "BadProgress" method, we create the progress object inside of our Task, i.e. we're creating the object inside the lambda expression that we have to define our Task. Since we're creating the progress object on our Task thread, the progress handler ("UpdateProgress") will be run on this thread -- not on the UI thread.

In the "GoodProgress" method, we create the progress object outside of our Task -- before we even create the Task. Since we're creating the progress object on our UI thread, the progress handler will also run on that thread. This is why we can safely interact with our UI elements from the "UpdateProgress" method here.

As a side note, our "progress" variable is captured by the lambda expression. Captured variables are pretty cool. You can learn more about them here: Video - Lambda Expression Basics.

What we've seen is that it's important to pay attention to where we create our Progress<T> objects. This is a subtle difference, but it can cause unexpected problems if we're not looking out for it.

Other Options
There are other ways that we can get this code to work. For example, we can get a reference to the Dispatcher of our UI thread and then use "Dispatcher.Invoke" in the "UpdateProgress" method to marshal things back to the UI thread. This will let us interact with the UI elements as we expect.

Another option is to move this code out of the code-behind of our form and into a separate view model class. In this scenario, our "UpdateProgress" method could update a property in the view model rather than updating the UI directly. This would eliminate the direct interaction with the UI elements -- that would all be handled through data binding.

These options have their pros and cons (and special quirks that we need to be aware of). It's always good to think about other ways of accomplishing a task so that we can pick the one that fits our needs.

Wrap Up
I came across this particular issue when I was helping another developer troubleshoot some code. In this code, there were 2 different Tasks that were created a little bit differently. One of them worked, and one of them didn't. On closer examination, we found that the progress objects were being created on different threads (just like our sample code here).

I will be exploring progress reporting in asynchronous methods a bit more in the future. In the meantime, be sure to take a look at the basics of Task, Await and Asynchronous Methods.

When dealing with multiple threads, it's common to run across issues just like this one. Task and Await make some things easier, but we still need to understand some of the underlying functionality so that we can use these appropriately -- and hopefully not be surprised when something strange crops up.

Happy Coding!

Sunday, July 19, 2015

Getting a Bit LINQ-ier

Last time we converted a file load method to be a bit more LINQ-y. The result was a compact and very readable method:


But should we be happy with this? Commenter "TomThumb" is not:
"Have you thought of using File.ReadLines() instead? It returns a lazily evaluated enumerable. It's arguably a bit more LINQy, and perhaps fits your use case a bit better (selecting subsets of the file)?"
Yep, this is probably a good idea. Let's take a closer look and do some informal metrics.

ReadAllLines vs. ReadLines
We'll start by looking at the difference between the methods ReadAllLines() and ReadLines(). Here are the method signatures from the documentation:


This shows us that "ReadAllLines" returns a string array, and "ReadLines" returns an string enumeration.

What's the difference? Well, "ReadAllLines" will read the entire file. "ReadLines" will read one line at a time as we enumerate through the file. If we stop enumerating, then the "ReadLines" will stop reading from the file. So this gives us an opportunity to short-circuit the file read.

And this is important because of how we're using the data from the file:


Pay attention to the "Take" method. Our file has about 40,000 records in it. But we may only "Take" 1,000 records, so there's no need for us to read the rest of the file.

This sounds good in theory, but let's put it into practice and see if we get a performance difference.

Comparing Performance
For this, we'll compare our original method (using "ReadAllLines") with a new method that uses "ReadLines". Here's the updated method:


And I'm curious about differences in the performance based on how much of the file that we read. So we'll do tests reading 1,000 records, 10,000 records, and the entire file (about 40,000 records).

1,000 Records
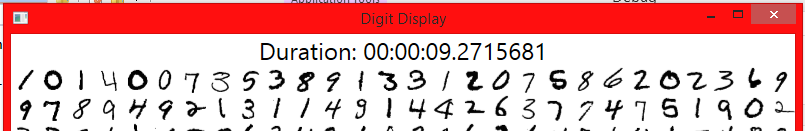
The application itself already has a duration timer built in, so we'll just use this. Now this shows the duration for the entire process which includes reading the file, processing the data into bitmaps, and loading them into a WPF list box.

The file load process is the fastest part of this process, so I expect to see the biggest differences when I only load a small portion of the data file.

Here are the results when we limit things to 1,000 records:

ReadAllLines - 1,000 Records
ReadLines - 1,000 Records

As expected, this is a pretty dramatic difference. Over several runs, the average with "ReadAllLines" was 1.316 seconds. The average with "ReadLines" was 0.951 seconds.

This makes sense since we don't have to read 39,000 records from the file, just the 1,000 that we're using. But let's keep going. I'm curious as to whether we'll keep that advantage with more records.

10,000 Records
The next tests were with 10,000 records. And the difference is still noticeable:

ReadAllLines - 10,000 Records
ReadLines - 10,000 Records

The average with "ReadAllLines" with 10,000 records was 9.311 seconds. The average with "ReadLines" was 9.042 seconds. Again, the bulk of the work being done here is creating bitmaps and loading the list box. But we see that there is about a 1/4 second difference in our results.

40,000 Records
For the last set of tests, I read the entire file which is about 40,000 records. This is where I was most curious. I wondered if the overhead of having the enumeration would out-weigh the efficiency of reading all the data into memory.

Let's look at the results:

ReadAllLines - 40,000 Records
ReadLines - 40,000 Records

This is where the tables turn -- but just a little bit. The average with "ReadAllLines" when we read the entire file is 37.811 seconds. The average with "ReadLines" is 37.877 seconds.

These results are so close (within a few 1/100ths of a second) that I don't feel right calling one "faster" than the other.

What this tells us is that when we "short-circuit" the file reading process (by only reading a portion of the file), we do get a definite advantage from "ReadLines". And when we read the entire file, we do not get a noticeable performance hit from using "ReadLines".

So, in this particular instance, it would be better for us to use "ReadLines".

Considerations
I have updated the code in the GitHub project: jeremybytes/digit-display. If you want to play with this code yourself, the file load method is in the FileLoader.cs file, and the read threshold is set in the MainWindow.xaml.cs file.

Here's our file loader method:


Now that we've made this method more LINQ-y by using a Read method that returns an IEnumerable instead of an array, we can look at taking this further.

I'm a big fan of enumerations and IEnumerable. There are some really cool things that we can do (particularly around lazy-loading). In this method, when we call "ToArray" it causes the enumeration to be evaluated. So any lazy-loading goes away right there. We force all of the records to be enumerated.

But we have another option. What if we were to push the enumeration further down in our application? So instead of returning a "string[]" from our "LoadDataStrings" method, we could return "IEnumerable<string>".

How would that affect our downstream code? Well here's where this method is used (in our MainWindow.xaml.cs file):


Notice that "rawData" is a string array, but this could just as easily be an "IEnumerable<string>". This would change how our code runs. This may be good or bad depending on our needs.

If we switch to an enumeration (rather than an array), then our "foreach" will end up going all the way back to our original enumeration from "ReadLines". This means that a line will be read from the file, then processed into a bitmap, then loaded into the list box before the next line is read from the file.

Is this a good thing? I'm not quite sure -- I'll need to think about this some more. One downside to doing things this way is that the file stays open during the entire process -- even while we're loading our UI controls.

With our current code (which calls "ToArray"), we're done with the file as soon as the file load method is finished. So the file can be closed before we start doing any processing on the data.

I'll leave things the way they are (with the arrays) for now. If you have a preference one way or the other, be sure to leave a comment.

Wrap Up
Thanks to "TomThumb" for making me think about things a bit more. Mathias actually does have a sidebar in his book that talks about the difference between "ReadAllLines" and "ReadLines". I appreciate the push to explore this a bit further.

When the question "How LINQ-y can you get?" comes up, the answer is often "a bit LINQ-ier". I'll look forward to exploring this (and a bunch of F#) as I dive deeper.

Happy Coding!