Showing posts with label IEnumerable. Show all posts

Sunday, July 19, 2015

Getting a Bit LINQ-ier

Last time we converted a file load method to be a bit more LINQ-y. The result was a compact and very readable method:


But should we be happy with this? Commenter "TomThumb" is not:
"Have you thought of using File.ReadLines() instead? It returns a lazily evaluated enumerable. It's arguably a bit more LINQy, and perhaps fits your use case a bit better (selecting subsets of the file)?"
Yep, this is probably a good idea. Let's take a closer look and do some informal metrics.

ReadAllLines vs. ReadLines
We'll start by looking at the difference between the methods ReadAllLines() and ReadLines(). Here are the method signatures from the documentation:


This shows us that "ReadAllLines" returns a string array, and "ReadLines" returns an string enumeration.

What's the difference? Well, "ReadAllLines" will read the entire file. "ReadLines" will read one line at a time as we enumerate through the file. If we stop enumerating, then the "ReadLines" will stop reading from the file. So this gives us an opportunity to short-circuit the file read.

And this is important because of how we're using the data from the file:


Pay attention to the "Take" method. Our file has about 40,000 records in it. But we may only "Take" 1,000 records, so there's no need for us to read the rest of the file.

This sounds good in theory, but let's put it into practice and see if we get a performance difference.

Comparing Performance
For this, we'll compare our original method (using "ReadAllLines") with a new method that uses "ReadLines". Here's the updated method:


And I'm curious about differences in the performance based on how much of the file that we read. So we'll do tests reading 1,000 records, 10,000 records, and the entire file (about 40,000 records).

1,000 Records
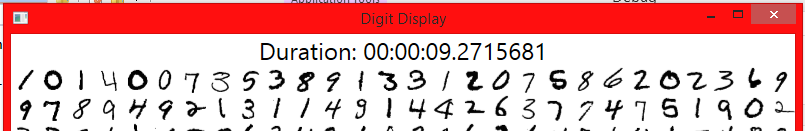
The application itself already has a duration timer built in, so we'll just use this. Now this shows the duration for the entire process which includes reading the file, processing the data into bitmaps, and loading them into a WPF list box.

The file load process is the fastest part of this process, so I expect to see the biggest differences when I only load a small portion of the data file.

Here are the results when we limit things to 1,000 records:

ReadAllLines - 1,000 Records
ReadLines - 1,000 Records

As expected, this is a pretty dramatic difference. Over several runs, the average with "ReadAllLines" was 1.316 seconds. The average with "ReadLines" was 0.951 seconds.

This makes sense since we don't have to read 39,000 records from the file, just the 1,000 that we're using. But let's keep going. I'm curious as to whether we'll keep that advantage with more records.

10,000 Records
The next tests were with 10,000 records. And the difference is still noticeable:

ReadAllLines - 10,000 Records
ReadLines - 10,000 Records

The average with "ReadAllLines" with 10,000 records was 9.311 seconds. The average with "ReadLines" was 9.042 seconds. Again, the bulk of the work being done here is creating bitmaps and loading the list box. But we see that there is about a 1/4 second difference in our results.

40,000 Records
For the last set of tests, I read the entire file which is about 40,000 records. This is where I was most curious. I wondered if the overhead of having the enumeration would out-weigh the efficiency of reading all the data into memory.

Let's look at the results:

ReadAllLines - 40,000 Records
ReadLines - 40,000 Records

This is where the tables turn -- but just a little bit. The average with "ReadAllLines" when we read the entire file is 37.811 seconds. The average with "ReadLines" is 37.877 seconds.

These results are so close (within a few 1/100ths of a second) that I don't feel right calling one "faster" than the other.

What this tells us is that when we "short-circuit" the file reading process (by only reading a portion of the file), we do get a definite advantage from "ReadLines". And when we read the entire file, we do not get a noticeable performance hit from using "ReadLines".

So, in this particular instance, it would be better for us to use "ReadLines".

Considerations
I have updated the code in the GitHub project: jeremybytes/digit-display. If you want to play with this code yourself, the file load method is in the FileLoader.cs file, and the read threshold is set in the MainWindow.xaml.cs file.

Here's our file loader method:


Now that we've made this method more LINQ-y by using a Read method that returns an IEnumerable instead of an array, we can look at taking this further.

I'm a big fan of enumerations and IEnumerable. There are some really cool things that we can do (particularly around lazy-loading). In this method, when we call "ToArray" it causes the enumeration to be evaluated. So any lazy-loading goes away right there. We force all of the records to be enumerated.

But we have another option. What if we were to push the enumeration further down in our application? So instead of returning a "string[]" from our "LoadDataStrings" method, we could return "IEnumerable<string>".

How would that affect our downstream code? Well here's where this method is used (in our MainWindow.xaml.cs file):


Notice that "rawData" is a string array, but this could just as easily be an "IEnumerable<string>". This would change how our code runs. This may be good or bad depending on our needs.

If we switch to an enumeration (rather than an array), then our "foreach" will end up going all the way back to our original enumeration from "ReadLines". This means that a line will be read from the file, then processed into a bitmap, then loaded into the list box before the next line is read from the file.

Is this a good thing? I'm not quite sure -- I'll need to think about this some more. One downside to doing things this way is that the file stays open during the entire process -- even while we're loading our UI controls.

With our current code (which calls "ToArray"), we're done with the file as soon as the file load method is finished. So the file can be closed before we start doing any processing on the data.

I'll leave things the way they are (with the arrays) for now. If you have a preference one way or the other, be sure to leave a comment.

Wrap Up
Thanks to "TomThumb" for making me think about things a bit more. Mathias actually does have a sidebar in his book that talks about the difference between "ReadAllLines" and "ReadLines". I appreciate the push to explore this a bit further.

When the question "How LINQ-y can you get?" comes up, the answer is often "a bit LINQ-ier". I'll look forward to exploring this (and a bunch of F#) as I dive deeper.

Happy Coding!

Wednesday, February 25, 2015

The LINQ Join Method: Deciphering the Parameters

In the last few articles, I've been answering questions that have come up during my presentations of lambda expressions and LINQ, including whether we should use the methods with or without a predicate and how the OfType method actually works. To continue, we'll take a look at the "Join" method.

I'm going to spend a bit of time with "Join" because it's come up twice in the last few weeks -- once in an email and once during my presentation at the Las Vegas Code Camp last weekend. When I do my presentations, I use the fluent syntax of LINQ (also known as the method syntax where we "dot" methods together). This leads to the following question:
How do you use "Join" using the fluent syntax?
The answer is that we just need to parse the parameters of the method. When we do this, we may find ourselves using 3 different lambda expressions as parameters. So lets take things step by step.

The completed code for this can be found in the "BONUSJoinSyntax" branch of the lambdas-and-linq repository on GitHub: BONUSJoinSyntax branch. The sample is in the "JoinSyntax" project.

[Update 4/24/2015: If you'd like to see a walkthough of this on video, check out Deciphering the Join Method]

The Sample Data
When we use "Join", we combine 2 separate but related pieces of data. For this, we'll use a collection of "Person" objects and a collection of "Order" objects. Let's take a look at the objects:

From People.cs
From Orders.cs

This shows our objects. Notice that the "Order" class has a "CustomerId" property. This matches up with the "Id" property of the "Person" class. So these are the properties we will use to join our data.

The data itself comes from the "People" and "Orders" classes. Notice that each of these has a single static method that returns an IEnumerable. This is just a hard-coded list of objects that we can use in our application.

Using "Join" With the Query Syntax
We'll start by looking at how we use "Join" with the query syntax -- it's a bit easier to understand. This code is in the "OrderReports.cs" file. The idea is that we have some methods to generate reports based on our data. Then we have a console application where we display the data.

Here's a simple LINQ query that joins data from our People and Orders:


Notice that this method returns an "IEnumerable<dynamic>". We'll come back to why we're using this in a bit. Before we get to that, let's look at the body of the method.

First we call "GetPeople" and "GetOrders" to get some data to work with.

Next we create a LINQ query using the query syntax. "from p in people" says that we want to get data from the "people" collection and give it the alias "p". Then we have the join: "join o in orders" says that we want to add data from the "orders" collection, and we'll give it an alias of "o". Then we have the "on" statement. This specifies how the data is related. In this case, we say that the "Id" property of a "Person" is the same as the "CustomerId" property of an "Order". (And this is exactly what we noted above).

Finally, we have a "select" statement. For this we are using an anonymous type, which is why we have the "new" keyword without a specific type name. Inside the curly braces, we specify that we want our anonymous type to include the "LastName", "FirstName", and "OrderDate" properties.

The "var" keyword was created just for this purpose: so that we could have types without names. This is still strongly-typed, but the type only has an internal name. We can see this by putting our mouse over the "var" next to "orderDates".


This shows that "orderDates" is an "IEnumerable<T>". Right in the middle we see that "T is 'a". "'a" is the internal name that the compiler gives to our anonymous type. And at the very bottom, we can see the "'a" consists of 3 properties: LastName, FirstName, and OrderDate. (Also notice that the types for the properties are filled in as well.)

Back to the return type for the method: "IEnumerable<dynamic>". The reason I used "dynamic" is so that we can use the anonymous type in our output. Using "dynamic" is not ideal (as we'll see in just a bit), and I'd probably make this a named type in a reporting library -- but we won't worry about this today.

Running the Report
Now that we have a query, let's use it to output some data. For this, we have a simple console application in our project: "Program.cs".

Here's the code:


This calls the "OrderDatesByCustomer1" method that we just created. Then it iterates through each item and outputs it to the console.

If we put the mouse over the "var" with "item", we'll see that this is a "dynamic" object:


This means that we get absolutely zero IntelliSense on this. So inside the "foreach" loop, when we type "item." we don't get any help from Visual Studio. We have to type in "OrderDate", "FirstName", and "LastName" ourselves (and spelling and capitalization count). This is the reason why I would not use "dynamic" in a production reporting library -- it is non-discoverable, meaning we have to have intimate knowledge of the data that is coming back. (I'll update this code in a future article, but let's not let it distract us from looking at the LINQ queries.)

Here's the output when we run the console application:


We have about 20 records, and the first thing I notice is that they would benefit from being sorted. If you're curious about where this order came from, the records are in the order of the people first (which is the "outer" part of our join) and then in date order secondarily (which is the "inner" part of our join). And these are simply the order that the data comes out of the methods (not alphabetical or by date).

Let's do a few things to make this data easier to look at.

Adding Sorting and Filtering
Let's start by putting our results into order by date. That makes most sense based on the data we get back from this report. For this, we'll add an "orderby" statement to our query:


This brings some order to our results:


Next we'll add a date range filter. For this, we'll add a "where" statement:


Notice that we added "startDate" and "endDate" parameters to our method. We use these in the query with a new "where" statement to filter our data.

We need to modify our console application a bit to add the parameters. In this case, we're looking for items in the month of December 2014:


And here's the output:


Now we have a smaller set of records to work with. And this gives us a result set for us to try to match by using the fluent syntax.

Using "Join" With the Fluent Syntax
Let's try to do this same thing using the fluent LINQ syntax. In my presentation for "Learn to Love Lambdas (and LINQ, Too)", I show how to read the method signatures for several LINQ methods, including "Where", "OrderBy", and "SingleOrDefault". I won't repeat all of that here because you can see that in the downloadable materials (and in a video series that I'll be publishing in the new few weeks).

But things get a bit confusing when we look at the method signature for "Join":


This has a lot of parameters. But they are related. The first 2 parameters describe the data collections that we are joining, the next 2 parameters describe how those collections are related, and the last parameter lets us transform the data into our resulting records.

Let's step through them one at a time.

IEnumerable<TOuter> outer
This is one of our collections of data. In our case, this will be our collection of "Person" objects. So wherever we see the generic type "TOuter", we can replace it with "Person". In addition, since this is an extension method, this will actually be the type that we extend. (For more information on Extension Methods, see "Quick Byte: Extension Methods".)

Note: I'm using the word "collection" in the general sense. These are technically enumerations which can also represent calculated sequences.

IEnumerable<TInner> inner
This is the other collection that we are joining to. In our case, this will be our collection of "Order" objects. So wherever we see the generic type "TInner", we can replace it with "Order".

Key Selectors
Next, we have the key selectors. These are one of the confusing parts. But this just gives us a way to specify which properties are related. So for our "Person" (remember, this is "TOuter"), we want to use the "Id" property, and for our "Order" (the "TInner"), we want to use the "CustomerId" property.

Func<TOuter, TKey> outerKeySelector
The syntax for this is a bit strange: "Func<Person, TKey>". From working with Func, we know that this is a method that should take a "Person" as a parameter and return a "TKey". What does this mean? It means that we just need to provide a property that we can use in "equals" comparisons.

Note: If you aren't familiar with Func<T>, then you can take a look at "Get Func<>-y: Delegates in .NET".

In technical terms, this means that we need something that implements the "IEquatable" interface. If we're using standard .NET types (such as int, string, date, etc.), we don't have to do anything special; this is all built in. But if we're using a custom type, then we may need to include the interface or provide a separate equality provider. But this is usually beyond what we need to do.

Since our "Person" class is keyed off of the "Id" property (which is an integer), the actual method signature will be "Func<Person, int>" -- a method that takes a "Person" as a parameter and returns an "integer". We'll see this in a bit.

Func<TInner, TKey> innerKeySelector
To associate our "Order" class with our "Person" class, we use the "CustomerId" property (an integer) of the Order. This means that our actual method signature for this is "Func<Order, int>" -- a method that takes an "Order" as a parameter and returns an "integer".

One thing to notice is that the generic type parameter for both of our key selectors is "TKey". This means that we must use the same type (in our case, it is an integer). This makes sense since we need to compare these based on equality. If they are different types, they they couldn't be equal.

Func<TOuter, TInner, TResult> resultSelector
This last parameter is also a bit confusing. The purpose of this is to specify what we want our output to look like. Just like with our "select" statement in the LINQ query, we need to specify what we want our output to look like. And we'll use an anonymous type for our output just like we did above.

If we fill in our generic types, this means that the method signature will be "Func<Person, Order, 'a>" -- a method that takes a "Person" and an "Order" as parameters and returns an anonymous type.

Putting This All Together
Here's our initial LINQ statement using the fluent syntax:


Let's go through these parameters one at a time.

people
The first parameter is the "people" object. This is the "IEnumerable<Person>" (a.k.a. "IEnumerable<TOuter>"). Since "Join" is an extension method, our first parameter has been moved to the front.

orders
The next parameter (first inside the parentheses) is the "orders" object. This is the "IEnumerable<Orders>" (a.k.a. "IEnumerable<TInner>").

p => p.Id
Next we have our first lambda expression. Remember, this is a "Func<Person, int>" in our case. So we have a lambda expression that takes a "Person" as a parameter (our "p") and returns an integer (the "Id" property).

With lambda expressions, we can name our parameters whatever we like; however, it is very common to use single character parameter names to keep lambdas short. I use "p" to remind me that this is a "Person" object.

This syntax is very similar to what we see when we use the "OrderBy" method to specify a property for sorting. (See "Learn to Love Lambdas" for details on this.)

o => o.CustomerId
Our next lambda expression is similar to the first lambda. This one is a "Func<Order, int>". So we have a lambda expression that takes an "Order" as a parameter (our "o") and returns an integer (the "CustomerId" property).

By returning these two properties ("Id" and "CustomerId"), we let our "Join" method know how to match up the records in the different collections.

(p, o) => new { p.LastName, p.FirstName, o.OrderDate }
Our last lambda expression is what we want our resulting data to look like. As noted above, this needs to match the signature "Func<Person, Order, 'a>" in this case. So we have 2 parameters: Person and Order, and I've named these "p" and "o" respectively.

The body of the lambda is the type that we want to return. And just like when we used the "select" statement above, we use the "new" keyword to generate an anonymous type. And this type specifies that we get the "LastName" and "FirstName" properties from the "Person", and the "OrderDate" property from the "Order".

A Lot of Pieces
So, it seems that we have a lot of pieces, but if we compare this to the query syntax, we see that we have the same information, just in a bit of a different format.

Query Syntax

Fluent Syntax

Once you get comfortable with lambda expressions, the fluent syntax becomes very readable. This is one reason why teach people about lambda expressions and encourage them to use them so that they become familiar.

Using the Method
Next we'll update our console application to use the new method:


This is much the same as we have with the other method. And our output is the same as our initial output:


Let's fix this up a bit like we did with our query syntax example.

Adding Sorting and Filtering
We'll add sorting to get things into date order. One nice thing about using the fluent syntax is that we simply "dot" our methods together.

So to add sorting, we just add an "OrderBy" method call:


The "OrderBy" method needs to return a property that we can sort on. In this case, we use the "OrderDate" property. Notice that the syntax for this lambda expression is similar to what we saw with the key selectors.

This makes sense when we look at the signature for "OrderBy":


This has a "keySelector" parameter which is a "Func<TSource, TKey>" -- just like the key selectors in the "Join" parameters. The difference is that this key does a comparison (testing whether something is "greater", "lesser", or "equal") instead of an equality comparison like we have with "Join".

As a side note, I used the parameter name "r" to stand for "result" -- this is the anonymous type that is returned from the "Join" method.

When we add the "OrderBy", our results are sorted:


Finally, we'll add a filter. For this, we'll use the "Where" method. This takes a predicate like we saw when we were looking at various LINQ methods and predicates earlier.

So we'll add some parameters to our method and use them in our "Where":


The predicate for "Where" is a "Func<TSource, bool>", meaning that we take a particular type as a parameter and return a true/false value. In our case, the "TSource" is the anonymous type that is returned from our "Join".

Again, I use "r" here to stand for "result" (which is our anonymous type), and the lambda expression body returns true or false depending on whether the "OrderDate" property falls within the specified date range.

The Fluent Syntax
Once we get several of these methods together, we start to see the fluent syntax. Our call ends up as "Join(...).Where(...).OrderBy(...)".

We end up "piping" the results from one method to another. "Join" returns an IEnumerable<T>, which we use as the input for "Where". "Where" returns an IEnumerable<T>, which we use as the input for "OrderBy". And "OrderBy" returns an IOrderedEnumerable<T> which we use as our result.

As we need more functionality (such as grouping or aggregation), we simply "dot" more methods together in the order that we need.

Updated Console Application
If we update our console application to pass in the date parameters, we can run our new method. The final console application runs both of our methods: the query syntax and the fluent syntax. This lets us see the results side-by-side (sort of):


And we can see that our results are the same.

As a reminder, the code is available on GitHub: BONUSJoinSyntax branch of jeremybytes/lambdas-and-linq.

Query Syntax or Fluent Syntax?
So the question you probably have is whether you should use the query syntax or the fluent syntax. The answer is that it is entirely up to you. As mentioned previously, it's most important that you are consistent.

My personal preference has been to use the fluent syntax. This is primarily because there are many, many LINQ methods to choose from that are not available in the query syntax. This means that we need to mix query syntax with fluent syntax to get full advantage of LINQ. Because of this, I have a tendency to use the fluent syntax. This lets me stay in the mindset of "Func" and lambda expressions. And since I really love lambdas, this isn't very hard for me.

Wrap Up
The good news is that "Join" is one of the more complex LINQ methods out there. That means if you can understand how to parse the parameters for "Join", you're probably all set to parse the parameters for all of the other LINQ methods as well.

"Join" does have a lot of parameters. But as we've seen, if we take things one step at a time (and don't get frightened off), it's not very hard to implement. Although there are 5 parameters, the first 2 are the collections that we are joining, the next 2 are lambda expressions to tell how the collections are related, and the last parameter is the data transformation to the output that we want.

With this under our belt, we're well on our way to using LINQ methods effectively in our code.

Happy Coding!

Tuesday, February 24, 2015

The LINQ OfType<TResult> Method: Cast or Filter?

So, we're continuing a bit more with LINQ questions that I've had come up recently. Last time, we looked at the difference between using a LINQ method with a predicate or without. Today, we move on to another useful filtering tool: OfType<TResult>.

I use this method in one of my samples and have had some questions come up:
When you use OfType, does it do a cast? What happens if the type doesn't match?
Let's take a closer look at OfType, what it really does, and where I find it useful.

OfType in Action
Last time, we looked at the SingleOrDefault method, and we used the following sample code that saves off a selected item in a list box and then re-assigns it after the list box is repopulated:

Saving the Selected Item
Re-assigning the Selection

Notice that we're using "OfType<Person>()" on the contents of the list box. This is because the "Items" property is not strongly typed.

Let's look at the signature of "OfType":


This is an extension method (just like every other LINQ method). And if we take a closer look, we see this takes an "IEnumerable" as a parameter. Notice that the parameter does *not* have a generic type parameter. So this is an IEnumerable that contains "object" elements. The return value is an IEnumerable *with* a generic type parameter. So the result is strongly typed.

Cast or Filter?
If we just look at the method signature, we might be inclined to believe that this method is doing a cast -- coercing the contained items from "object" to the type of our choice. But this is not what is happening.
OfType<TResult>() is a Filter (not a cast).
The reality is that the "OfType" method is simply a filter, just like many other LINQ methods.

No Exceptions
This also means that if the type does not match the object in the IEnumerable, it does *not* throw an exception. Instead, it simply does not return that record.

A Useful Tool
I find the "OfType<TResult>" method to be a useful little tool when I want to convert an object-based collection into a strongly-typed collection. (I'm using "collection" in the general sense here. Technically, we're dealing with iterators (IEnumerable), and these do not need to represent a collection of objects; they could just a easily be a sequence that is generated on-the-fly as the elements are requested.)

In our case, I want to use LINQ methods against the "Items" property of a WPF list box. If we look at the "Items" property, we see that is an "ItemCollection":


And if we look at "ItemCollection", we see that it implements "IEnumerable" (which represents items of type "object"), but not "IEnumerable<T>" (a strongly-typed enumeration):


Pretty much all of the LINQ methods work on "IEnumerable<T>", like we saw with our "SingleOrDefault" method last time:


This means that we need to turn our "IEnumerable" into a strongly-typed "IEnumerable<T>". And that's exactly what "OfType<TResult>" does for us.

Where I Use OfType<TResult>
I find myself using the "OfType" method when dealing with UI controls, like in the examples we saw today. This is because the collection controls are designed to handle pretty much anything we can throw at them -- and that's one of the really cool things about XAML controls and XAML data binding.

But this also means that if we need to pull data out of a UI control, we need to cast it in order to work with it more easily. And that's exactly what "OfType" lets us do.

Again, this isn't doing a cast, but the outcome is pretty much the same. We put an IEnumerable of object in one end and get a strongly-typed IEnumerable<T> out the other end.

When we're using data binding, we often don't need to worry about this. If we have a strongly-typed collection in our view model, we can data bind it to the UI control with no problem at all. And the data binding infrastructure takes care of any type changes for us.

But there are times when we need to pull things out manually in order to work with them. In those situations, the "OfType" method makes things much easier.

Wrap Up
I tell people all the time that they need to take a look at all of the LINQ extension methods that are available to us. Go take another look right now: IEnumerable<T> Extension Methods. This list contains lots of useful methods. And there are a few gems in there that you may not know exist.

LINQ is one of my favorite things. That's probably because I deal with collections of in-memory objects all the time. I get data from a data source, and then I need to manipulate it a little bit for the UI. LINQ lets me do that very easily -- and the end result is happier users.

Next time, we'll take a look at the "Join" method. This is a little more complex, but it's not too hard to understand the parameters when we take them one at a time. So stay tuned for more on LINQ.

Happy Coding!

Sunday, December 9, 2012

Book Review: Professional .NET Framework 2.0

So, I'm a bit behind on commenting on the tech books that I've read recently.  The first is Professional .NET Framework 2.0 by Joe Duffy (Amazon link).  Note: this book is from 2006 and is currently out-of-print; fortunately there are several sellers in the Amazon marketplace how have new or used copies.

Now, it may seem strange to be reading a .NET 2.0 book from 2006 in 2012, and I would normally agree with that thought.  But this book has a few key advantages to some others.  It was recommended to me as a way to "fill in some gaps", and it has done just that.  I'm not really going to review the entire book here, just provide some comments and samples on what made this valuable to me.

Big Plus - Joe Duffy
One of the big advantages to this book is its author.  Joe Duffy was a program manager on the CLR (Common Language Runtime) team at Microsoft.  This means that he knows the internals of the CLR and not just the external APIs.  And this book provides plenty of insight into the internals, as we'll soon see.

Looking into IL
The biggest learning that I took away from this book is a better understanding of IL (Intermediate Language).  This is what the compiler generates from your C# or VB.NET code (or any other .NET language).  It is not machine code, but it has more in common with assembly language than a 3G or 4G language that business programmers generally use.  The IL will get Just-In-Time compiled (jitted) to the instructions that the machine will actually run.

Now, I've known about IL for a long time, and I've seen people who look at it.  Historically, I haven't been one to dig into it myself.  But after having Joe Duffy explain IL and how language components get transformed into IL, I've been more interested in digging into the IL to see how things are generated.

Setting up ILDASM
The .NET SDK ships with a way to look at the IL -- this is ildasm.exe (for IL Disassembler).  Here's where it's found on my 64-bit machine:

At this location, you'll find a file called "ildasm.exe".  You can run this directly, and then use the File -> Open dialog to locate a .NET assembly.  But what's even better is to add this as an External Tool in Visual Studio. Then you can just run it against whatever project you're currently working on.

To configure this in Visual Studio (I'm using VS2012, but it's the same in earlier versions), just go to the "Tools" menu and select "External Tools...".  From here, you can Add a new tool.  When you're done, it should look something like this:


For the Title, you can use whatever you'd like; this is just what will appear on the Tools menu.  The command should be the fully-qualified location of the "ildasm.exe" file.

The "Arguments" and "Initial directory" settings are a little more interesting.  Notice the arrow to the right of the text box.  This gives you a number of variables that you can choose from.  For the "Arguments" property, I chose 2 variables.  The first "$(TargetName)" is the name of the assembly that is currently active.  Note that this does not include the file extension, just the name.  Because of this, we also need "$(TargetExt)".  This will give us ".exe" or ".dll" depending on what type of assembly we are building.

The "Initial directory" setting tells us where the assembly (from the argument) is located.  In this case, "$(TargetDir)" means the output location of the file.  So, if we are in the Debug build, it will be "<project path>\bin\Debug\".

After clicking "OK", we now have a new item on our tools menu.

Using ILDASM
So, now that we have Visual Studio configured so that it's easy to get to ildasm, let's see what this looks like.  I created a very simple console application that just outputs "Hello, World!" (using Console.WriteLine).  I don't think I need to reproduce the code here ;-)

With this project open, I just need to go to Tools -> ILDasm, and it opens up the compiled assembly.  Drilling down a bit, we get to the Main method:


The name of my application is "ILDamsTest.exe", and we traverse the tree to get to the Main method.  If we double-click on the Main method, we get to the disassembled IL:


Here, we see the IL for the most basic console application.  Going through the instructions, we have the following.  First, "nop" is a "no op", meaning no operation is performed.  This is here so that the compiler can attach a breakpoint to a part of the code that doesn't perform an operation (for example, attaching a breakpoint to the opening curly-brace of the method).

Next, we have "ldstr" which loads the string "Hello, World!" onto the stack.  Next, we have a "call" that runs the Console.WriteLine method.  Note that the IL has the fully-qualified name for this, including the assembly (mscorlib) and the namespace (System).  We can see that this method takes a string argument, and it gets this from the top of the stack.  Since we just pushed "Hello, World!" onto the stack, this string will be used for the parameter.

Next we have another "nop", for the closing curly-brace, and finally the "ret" that returns from the method.

Pretty simple.  Now let's look at the same thing compiled in "Release" mode:


Notice that we've gone from 5 instructions down to 3; the "nop" instructions are gone.  The compiler removed them since we can't breakpoint into release code.

More Fun with IL
So, after I started looking just a little bit at IL, I've become much more curious about how the compiler generates IL.  For example, I like to see what code is generated by the "shortcuts" that the C# language and compiler give us.

Here are 2 equivalent blocks of code:

Now, the "foreach" loop will work on any object that implements the IEnumerable interface.  That interface has a single method ("GetEnumerator").  (Note: if you want more information on IEnumerable, you can reference the series of articles at Next, Please! A Closer Look at IEnumerable.)

So, the first block of code shows how to use the Enumerator directly (with MoveNext and Current), and the second uses the "foreach" construct.  We would expect that these two blocks would compile to the same IL.

But if we look at the IL, we find that they are not compiled to the same code.  They are close, but when  "foreach" is compiled, it is automatically wrapped in a try/finally block.  Try this yourself to see.

And so started my journey into IL and the fun behind it.  Some other interesting places to look include anonymous types (to see that the compiler does create a type with an internal name), delegates (to see what a delegate is behind the scenes), lambda expressions, and many others.  You will probably come across some compiler optimizations that surprise you as well.

Note: I won't include any links to IL references because I haven't found any good ones.  If you want the specification, you can search for "ECMA 335", with a caveat that this is the 500+ page specification document (not overly readable).  Professional .NET Framework 2.0 provides a compact reference for IL (along with a number of examples).

[Update: I found an online reference. It's not very descriptive, but it has the CIL Instructions: http://www.en.csharp-online.net/CIL_Instruction_Set.]

Wrap Up
So, even though Professional .NET Framework 2.0 is 6 years old, I found many useful things in it.  There are plenty of good topics (including a look at the Garbage Collector and also multi-threading).  As you can probably tell, I've become comfortable looking at the IL -- something that I never would have done before.  An appendix is dedicated to the IL operations so that you can parse the output of ildasm yourself.  Once you start looking at the IL, you come across all sorts of interesting things that will give you a better understanding of how the code you write gets transformed into something closer to what the machine will actually run.

This is not a resource for a beginner or someone new to C#, but it is a great way to take a deeper dive into some of the fundamentals of the .NET Framework.

Happy Coding!

Friday, May 25, 2012

Next, Please! - A Closer Look at IEnumerable (Part 5 - Usage Tips & Wrap-up)

This is a continuation of "Next, Please! - A Closer Look at IEnumerable".  The articles in the series are collected together here: JeremyBytes - Downloads.

Last time, we took a look at the Strategy pattern and then used that pattern to create a StrategicSequence that allows us to pass in whatever algorithm we want to generate the sequence.  This gives us an class that can be extended without modifying the class directly and gives the application (client) the opportunity to select which algorithm to use.

Today, we'll explore some tips for using classes that implement IEnumerable<T> (whether they are classes we create ourselves or classes from the .NET Framework).

IEnumerable<T> Tips
As we've seen, IEnumerable<T> is a fairly simple interface that gives us access to a lot of functionality.  But, there are a number of things we should take into consideration when we decide on how to use that functionality in our applications.

Tip: Don't Modify Collection Items in a foreach Loop
This is actually a "don't ever do this" rather than a "tip".  When using a foreach loop (or using the enumerator more directly), it is very tempting to modify the items as you are iterating them.  However, this only causes problems (some more obvious than others).

First, what happens if we try to add or remove an item in a foreach loop?  Consider the following code:


The idea behind this code is that we iterate through our people collection (with a foreach loop).  If the FirstName property of the person is "John", then we want to remove that person from the collection.  Then we want to add that person object to the list box of our UI.

But we are not allowed to add or remove items from a List<T> while we are enumerating it.  This code will compile just fine, but if we try to run it, we get the following Exception:
System.InvalidOperationException: "Collection was modified; enumeration operation may not execute."
So adding and removing items is not allowed.  What about modifying items?  That's where things get a bit interesting.  Let's look at the following code:


Inside the foreach loop, we first add the "person" to the list box of our UI.  Then if the FirstName property is "John", we change it to "Test".  We would expect that we would see the "John" items in the list box (since we add thems before changing them).  But here is the output:


As you can see, "Test" is showing up in our output!  This is not the output we would expect from this code.  The strangeness is a result of trying to update a collection while we are iterating that collection.

Based on these problems, we never want to modify a collection as we are iterating it.  In most situations, it is fairly easy to come up with another solution that accomplishes our same goals by handling the modification outside of the iteration.  Note: "for" loops do not exhibit this same issue since they do not use the enumerator; this is sometimes a good solution (but not always).

Tip: Avoid Creating A Custom Class
In our samples from Part 3 and Part 4, we created classes that return a sequence of numbers.  I purposely chose this type of sequence because we could base our "MoveNext()" on a calculation of some type.  In most situations, though, there is no need to create a custom class that implements IEnumerable<T>.

As mentioned in Part 1, almost every .NET collection implements the IEnumerable interface.  This includes arrays, generic lists, linked lists, queues, stacks, and dictionaries.  Generally speaking, if you find yourself in a situation where you need an IEnumerable implementation (because you need to iterate through a set of items), you will probably also need the more advanced collection functionality that you get with one of these framework classes.

In most scenarios, we should start by looking at the .NET collection classes.  One of these classes will mostly likely fulfill our needs.

Tip: Use a Custom Class to Hide Functionality
Sometimes the .NET collections have more functionality than we want to expose in our application.  For example, let's say that we need a collection that we can iterate through, but we don't want to use "List<T>" because we don't want the collection items to be directly modifiable.

Here's an example how we can use a custom class to wrap a List<T> object and hide its functionality:


We have a custom class that implements IEnumerable<T> (so we'll get our iteration functionality).  The class contains a private list that is not visible externally.  The list gets initialized by the class constructor.

Notice the GetEnumerator() method.  Instead of implementing our own IEnumerator<T> class or using "yield return", we are simply calling the internal list's GetEnumerator() method.  This is perfectly valid.  And it makes sense to do it in this situation -- the IEnumerator is already implemented by an object in our class, so there is no reason for us to create a custom implementation.

The result of this class is that we have a list of objects that we can iterate through, but we have no way to modify the collection externally.  Note that we are also hiding the other List<T> members in the private class (such as IndexOf), but we still have access to all of the IEnumerable<T> extension methods, such as Single() and Where(), if we are searching for particular items in the collection.

Tip: Use a Custom Class to Reduce Overhead
Sometimes we don't need all of the functionality provided by a collection object.  In that case, we can create a custom class that implements IEnumerable<T> that only has the functionality that we need.  This is exactly what we did with our sequence classes: IntegerSequence, FibonacciSequence, and StrategicSequence.

We did not need any of the overhead associated with a collection since our values are calculated as we need them.  Granted, our example is a rather contrived one.  But it demonstrates that it is possible and practical to have a class that implements IEnumerable<T> without other collection-type functionality.

IEnumerable<T> Review
The last several articles have shown a lot of different aspects of IEnumerable<T>.  Let's do a quick review:

IEnumerable<T> Interface Members
We started by looking at the IEnumerable<T> and IEnumerator<T> interfaces. We saw the methods and properties (such as GetEnumerator(), Current, and MoveNext()) that are specified in each.

Iterator Pattern
The Iterator pattern is described by the Gang of Four as a way to get items one-by-one from a collection -- "Next, Please!"  The IEnumerable<T> interface describes an implementation of this pattern.

foreach Loop
We can use a "foreach" loop to iterate through the items contained in any class that implements IEnumerable<T>.  This is an easier way to interact with the class then if we were to explicitly call the GetEnumerator() method along with MoveNext() and Current.

Extension Methods
Extension methods give us a way to add functionality to a class without modifying the class directly.  From a syntactic standpoint, extension methods behave as if they are native methods of the class.

IEnumerable<T> and LINQ
LINQ (Language INtegrated Query) provides us with a myriad of extension methods on the IEnumerable<T> interface.  This gives us the ability to write queries and perform all types of functions against any class that implements IEnumerable<T>, including (but not limited to) filtering, sorting, aggregation, and grouping.

Implementing IEnumerable<T>: IntegerSequence
Our first custom implementation of IEnumerable<T> let us take a look at the members of IEnumerable<T> and IEnumerator<T>.  We saw what each member is designed for, and we used the members to create a class that returns a series of consecutive positive integers.

yield return
"yield return" provides us with shortcut syntax when implementing an enumerator.  It lets us create a method that retains its state between calls.  Using this, we can mimic a full implementation of the IEnumerator<T> class with a single method.

Implementing IEnumerable<T>: FibonacciSequence
Our second custom implementation of IEnumerable<T> was a bit more complex.  We used what we learned from the simple IntegerSequence and created a class that returns the Fibonacci sequence, where each value is the sum of the previous two values.

Strategy Pattern
The Strategy pattern is described by the Gang of Four as a way to create a set of encapsulated, interchangeable algorithms.  We took a look at the advantages of using the pattern as well as some of the negative consequences.

The StrategicSequence Class
Our final custom implementation of IEnumerable<T> let us explore the Strategy pattern in a bit more detail.  The StrategicSequence class accepts a strategy (the algorithm for calculated the sequence) as a constructor parameter.  This lets us externalize the algorithms into separate classes.  We created the IntegerStrategy, FibonacciStrategy, and SquareStrategy that implemented these algorithms.  And we saw the advantages that this gave to our particular application.

Wrap Up
In summary: IEnumerable<T> is awesome!  Okay, I might be a little too excited about an interface, but it offers us a ton of functionality with very little effort.  Implementing the interface ourselves is not that difficult, and even better, there are lots of implementations already provided for us in the .NET framework.

I find myself using the LINQ extension methods all of the time.  It's so easy to just drop in a Where() method to do a filter of a collection, or an OrderBy() to sort the list, or a Single() to pick out a specific item. And all we need to take advantage of this functionality is a class that implements IEnumerable<T> and a good understanding of lambda expressions (but we've already got that, right?).

Hopefully you are as excited about IEnumerable<T> as I am (or at least a bit more interested than you were when we started).  Learning the features included in the .NET framework lets us take advantage of extremely powerful functionality that is already there just waiting for us.

Happy Coding!